LoginSign Up

Brandon Handoko

Data @ Scale AI
71K insights
Visible to Brandon
Brandon won't be able to see or reply to your conversation in incognito mode
Ask about me
Learn from my insights
Jam on a problem
About
Say hi — first dot last at gmail / twitter @brndnwll
San Francisco Bay Area
Brandon Handoko

Sumit Minocha

@sminocha_

Really excited to share our first benchmarks @ThriveHoldings: individual tax prep and helpdesk ticket resolution. The first two in a larger suite based on real world workflows across our businesses. I like to think about our product philosophy as “1000 evals.” Evals are how we actually have a POV on what the models are doing well for our operators and where the product needs to improve. The problem is what "good" looks like keeps moving as models get better and as agents can take on more work. To allow the evals to evolve with the work, we structure the UX such that the product is the grader. A user’s corrections to output become graded examples, unedited = ground truth. M&A, entity tax, and other core workflows coming soon! http://evals.thriveholdings.com
Really excited to share our first benchmarks @ThriveHoldings: individual tax prep and helpdesk ticket resolution. The first two in a larger suite based on real world workflows across our businesses.

I like to think about our product philosophy as “1000 evals.”

Evals are how we actually have a POV on what the models are doing well for our operators and where the product needs to improve.

The problem is what "good" looks like keeps moving as models get better and as agents can take on more work. To allow the evals to evolve with the work, we structure the UX such that the product is the grader. A user’s corrections to output become graded examples, unedited = ground truth.

M&A, entity tax, and other core workflows coming soon!

http://evals.thriveholdings.com
View on 𝕏
Brandon Handoko

Long Phan

@longphann_

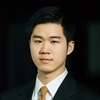
Gemini 4 Argon and Muse Wonder on HLE-Diamond. Gemini 4 Argon competes with GPT-6.1 Sol and Opus 5.5, but uses ~5x more output tokens than GPT-6 models.

Gemini 4 Argon and Muse Wonder on HLE-Diamond.

Gemini 4 Argon competes with GPT-6.1 Sol and Opus 5.5, but uses ~5x more output tokens than GPT-6 models.
View on 𝕏
Brandon Handoko

Daniel Rupawalla

@danielrupawalla

yep ofc, many an issue will have to be hill-climbed to do something like this, and i wouldn’t be surprised if they’re already working on stuff in this line, but just haven’t heard anyone talking about it yet which is disappointing

View on 𝕏
Brandon Handoko

Chris Khoo

@khooeee

After using a ton of agent development environments in my day-to-day, I started making my own in my spare time. And absolutely enjoy using it. Will talk about it from time to time, but if anyone is interested in playing with it, it's at: https://github.com/khooeee/switcheroo/

After using a ton of agent development environments in my day-to-day, I started making my own in my spare time.  And absolutely enjoy using it.  Will talk about it from time to time, but if anyone is interested in playing with it, it's at: https://github.com/khooeee/switcheroo/
View on 𝕏
Brandon Handoko

BridgeMind

@bridgemindai

Muse Wonder is benchmaxxed. Meta says it beats the competition on the key benchmarks. On the BridgeBench lava lamp test it built a red cylinder. No glass. No lava. I've never seen a model this benchmaxxed in my life.

View on 𝕏
Get the App
New to SuperMe?

Sign up free to work on your questions with people who've been there, like Brandon.Download SuperMe for the best experience